GPU and Specialized Sandboxes
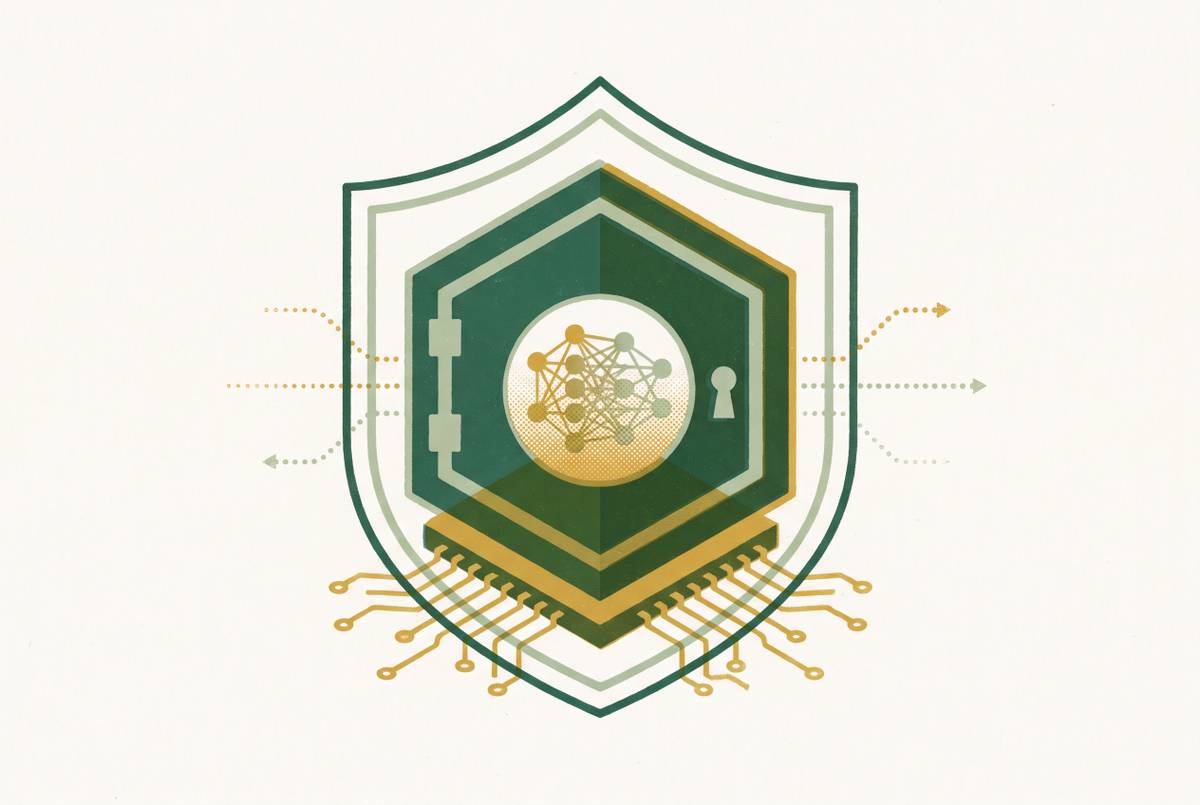
Confidential Computing Enclaves for Sensitive AI Workloads
Hardware isolation and attestation together protect AI models and prompts during processing.
Tomás Echeverría
· 9 min read
Hardware isolation and attestation together protect AI models and prompts during processing.
Agents need accelerators to run untrusted code safely and fast.
Hardware partitioning lets untrusted inference workloads safely share one GPU.
Executing unreviewed AI code requires hardware isolation between guest and host kernels.
Wasm sandboxes secure AI tool execution through deny-by-default capabilities.
Four key dimensions determine whether an AI sandbox platform can handle production workloads safely.
Four metrics beyond uptime determine whether a sandbox can reliably run AI-generated code.
Security boundaries and startup latency determine which sandbox fits your agent workload.
Firecracker keeps state between invocations; gVisor trades isolation density for instant startup.
How billing models shape which agent workflows platforms can serve economically.
Compliance, latency, and operational burden determine whether managed or self-hosted makes sense.